Hugging Face Blog发布于 08/21 08:00
Measuring benchmark optimization in speech recognition
(翻译)衡量语音识别中的基准优化
We’re on a journey to advance and democratize artificial intelligence through open source and open science.

(翻译)衡量语音识别中的基准优化
We’re on a journey to advance and democratize artificial intelligence through open source and open science.
(翻译)函数级执行反馈用于代码偏好优化
Abstract page for arXiv paper 2608.23632: Function-Level Execution Feedback for Code Preference Optimization
(翻译)利用强化学习增强的智能体搜索生成生物医学事实核查报告
Abstract page for arXiv paper 2608.23811: Generating Biomedical Fact-Checking Reports with RL-Enhanced Agentic Search
(翻译)Open ASR 排行榜新增首个全球南方语言
We’re on a journey to advance and democratize artificial intelligence through open source and open science.

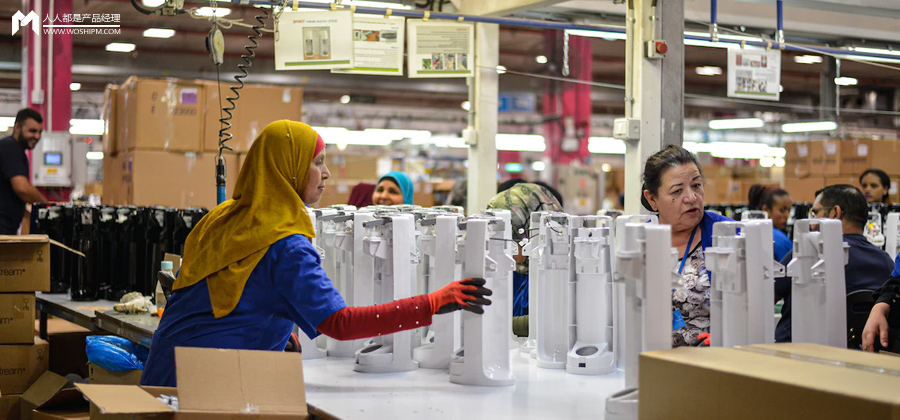
从NLP时代到大模型时代,AI质检的落地成本骤降十倍,准确率却从半年苦练的80%跃升至开箱即达的98%。本文通过两个真实案例,对比不同技术路线下的架构、训练与成本差异,揭示技术革命如何将AI质检从大公司专属的奢侈品,变为中小企业随手可用的生产力工具。
(翻译)检索关系,检测谬误:一种用于政治辩论分析的RAG方法
Abstract page for arXiv paper 2608.27471: Retrieving Relations, Detecting Fallacies: A RAG Approach to Political Debate Analysis
(翻译)思考消耗令牌:更多结构何时物有所值
Abstract page for arXiv paper 2608.27506: Thinking Costs Tokens: When More Structure is Worth the Price
(翻译)Nemotron 3.5 内容安全审核器:一款紧凑的多模态、多语言且支持推理的内容安全审核器
Abstract page for arXiv paper 2608.27548: Nemotron 3.5 Content Safety Moderator: A Compact Multimodal, Multilingual, and Reasoning Enabled Content Safety Moderator
(翻译)BenchMIRT:LLM 基准测试究竟在测量什么?
A Blog post by Ai2 on Hugging Face

(翻译)基于指令微调小语言模型的渐进式老年人金融诈骗增量风险评估
Abstract page for arXiv paper 2609.00005: Incremental Risk Assessment of Progressive Elder Financial Scams via Instruction-Tuned Small Language Models
(翻译)大语言模型中的长程状态追踪:通过深层依赖工具调用序列执行 MD5
Abstract page for arXiv paper 2609.00012: Long-Horizon State Tracking in LLMs: Executing MD5 through a Deep Sequence of Dependent Tool Calls
(翻译)WinSyn:面向真实企业问答评估的自动化流水线
Abstract page for arXiv paper 2609.12171: WinSyn: An Automated Pipeline for Realistic Enterprise Question-Answering Evaluation
(翻译)检测大语言模型中的幻觉:追踪上下文共享受损的拓扑特征
Abstract page for arXiv paper 2609.21096: Detecting Hallucination in LLMs: Tracing the Topological Signatures of Impaired Context Sharing
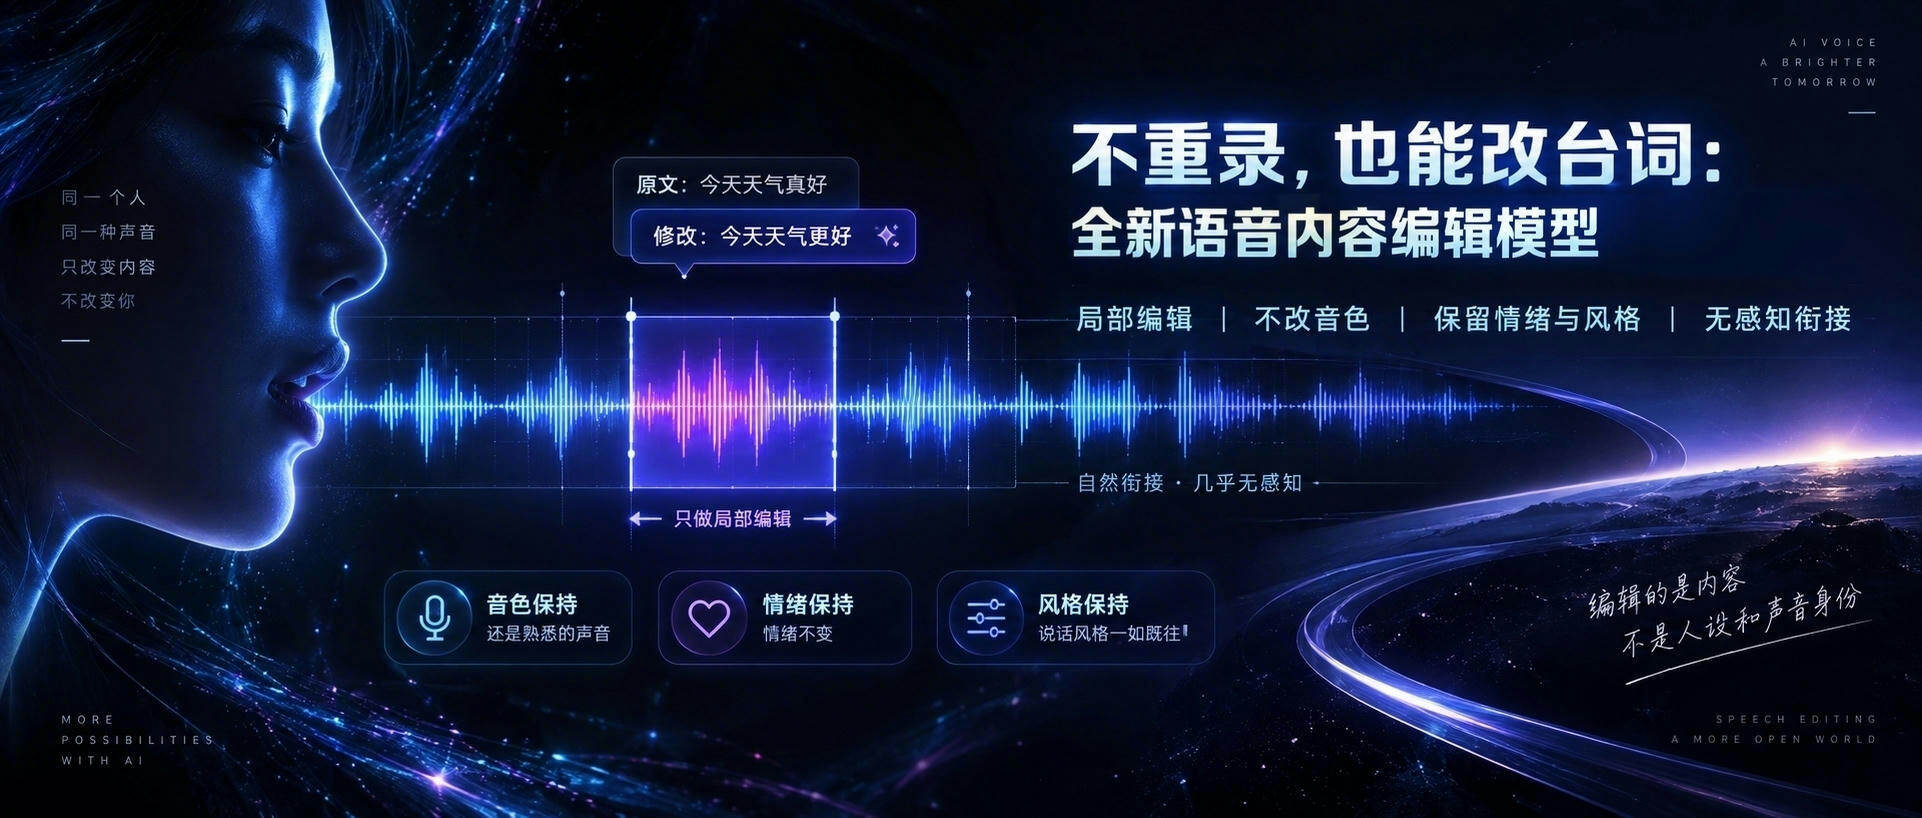
说错一个词,不必重录一条片。输入原始音频,再用一句自然语言说明“要改哪里、改成什么”,语音内容编辑模型就能直接改写声音里真正说出来的话,并尽量保留原说话人的音色、语气和上下文表达。
(翻译)MEA:用于忠实模型解释的奖励驱动多智能体系统
Abstract page for arXiv paper 2610.02480: MEA: A Reward-Driven Multi-Agent System for Faithful Model Explanations